Enterprise AI Agents: Identity, Accountability, and What It Takes to Run Them
Enterprise AI agents act on real systems, which makes identity and accountability the hard problem — not capability. Use cases, governance, integration, evaluation and what to deploy first.
12 min readby Prithvi
Most writing about enterprise AI agents is about what they can do. The harder question, and the one that actually decides whether a deployment survives a security review, is simpler to state and harder to answer:
When an agent does something, who did it?
An AI agent that reads a record, updates a system or sends a message has acted inside your company. Something has to establish which human that action traces back to, what authority it carried, and how anyone would reconstruct it later. Companies that answer this early deploy agents widely. Companies that treat it as a compliance task to handle after the pilot tend to stall between pilot and production.
This guide covers what enterprise agents are, where they produce value, how identity and accountability work, what governance is required, how to integrate them, and how to evaluate them before committing.
What makes an agent different
The category boundary is narrow but consequential. A traditional AI system produces output for a human to act on. An agent acts.
Four capabilities define it:
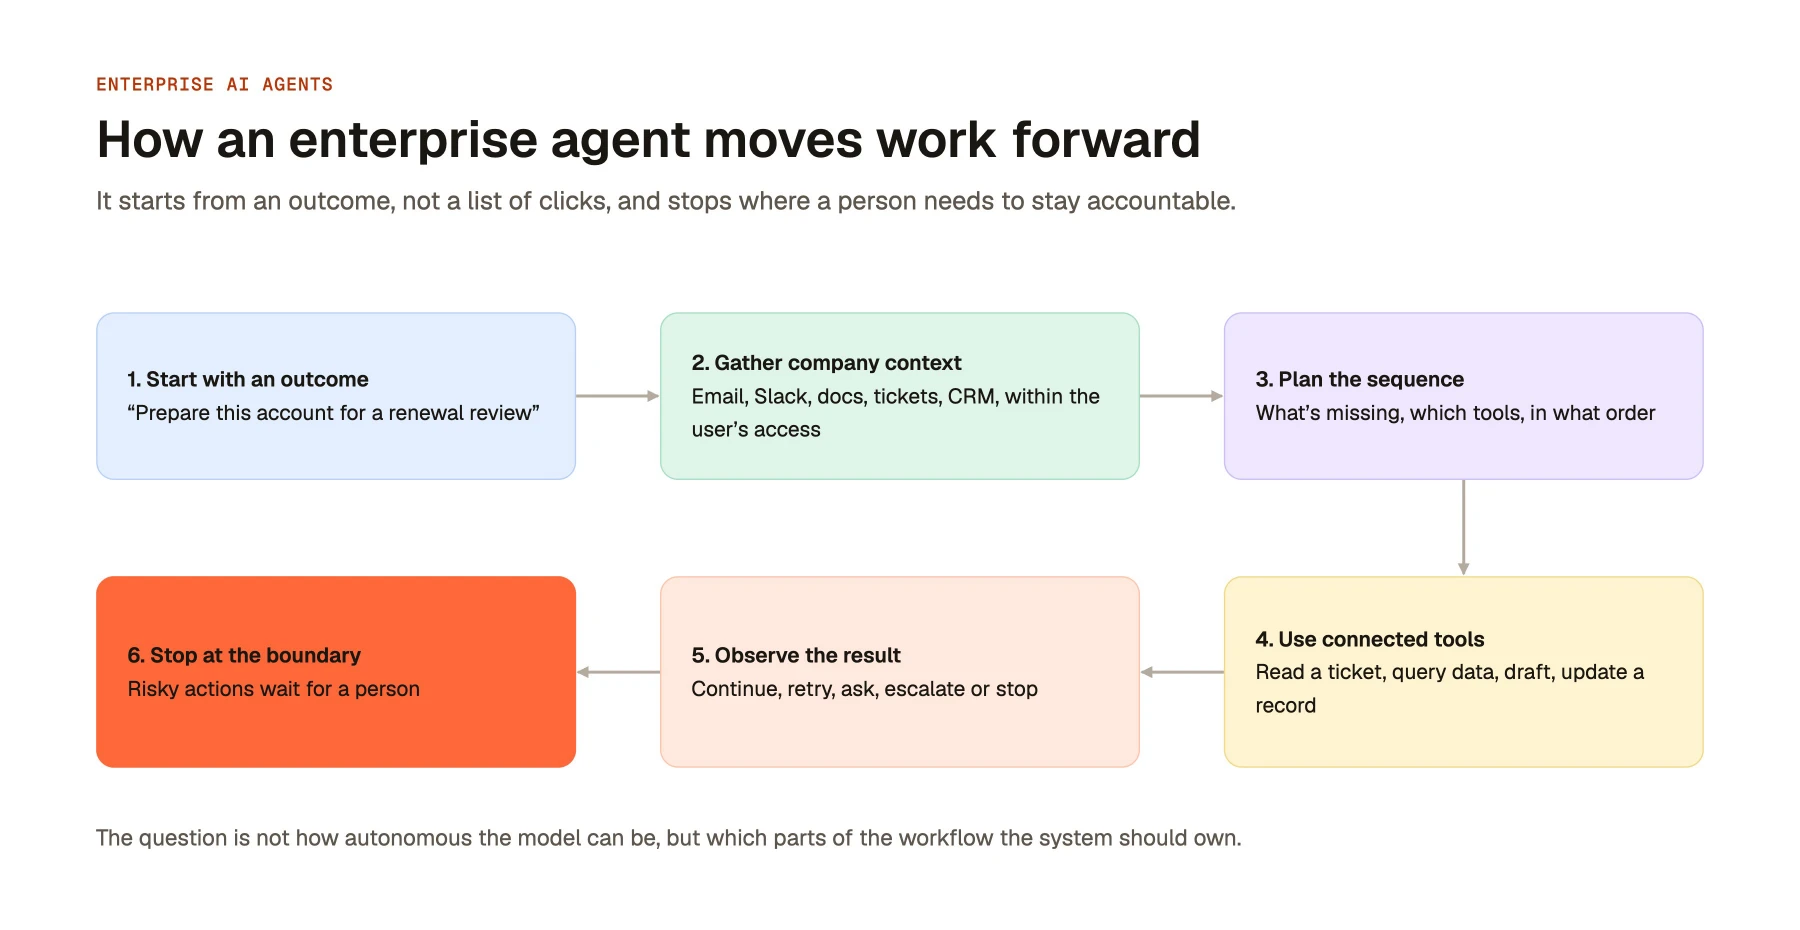
- Planning — decomposing an objective into steps rather than executing a script
- Tool use — calling real systems via function calling and connectors
- State — carrying what it learned at step three into step seven, through persistent company memory
- Adaptation — changing approach when a step fails, rather than halting
How the category evolved
The progression is worth naming, because each stage's assumptions still shape how people evaluate the next.
Dashboards told you what happened. Chatbots answered questions about it. RPA automated fixed sequences, deterministically and brittlely. Assistants generated useful text from the context you provided. Agents own a process end to end.
The question has shifted from "can AI help with this task?" to "can an agent own this process?" and that second question carries governance weight the first never did.
The current frontier is multi-agent work: several specialised agents coordinating, one's output feeding another's input, with an orchestration layer managing handoffs. See multi-agent system and Agentic AI vs AI Agents.
Identity and accountability
This is the part most enterprises underestimate, and it's where the strongest content on this topic concentrates.
Non-human identities already outnumber human ones
In most large technology estates, service accounts, API keys and integrations already outnumber employees. Those identity systems were designed for applications and service accounts — predictable, scoped, long-lived. Agents are none of those things: they act variably, on behalf of different people, across many systems.
The service-account trap
The fastest way to connect an agent to your systems is to give it a service account with broad access. It's also the decision that quietly destroys your permission model.
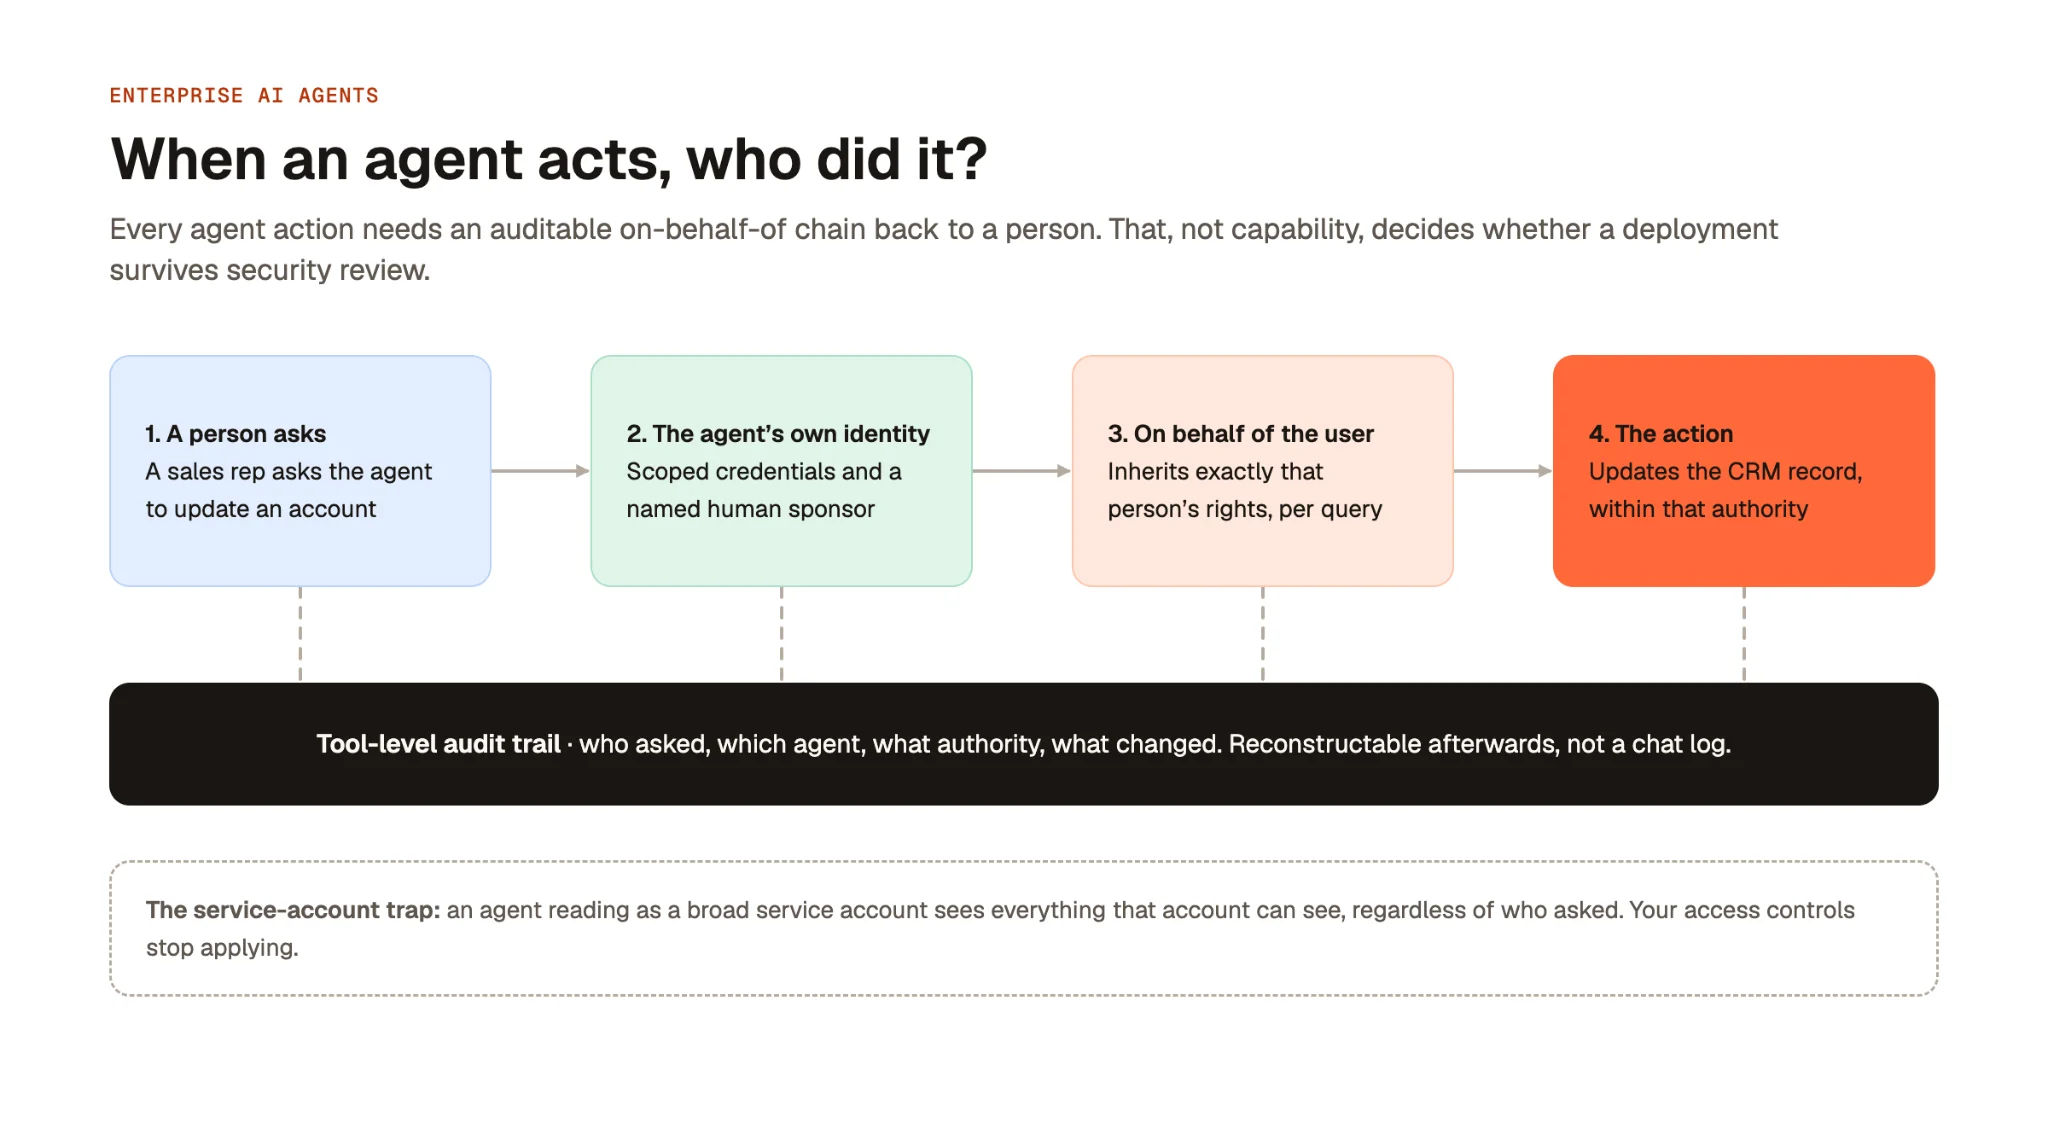
An agent reading as a service account sees everything that account can see, regardless of who asked. Every query becomes a potential disclosure path, and your carefully maintained access controls stop applying the moment the agent is involved.
The alternative is permissions-aware AI: the agent acts on behalf of a specific user and inherits exactly that user's rights, per query. This requires an identity graph mapping identities across systems, and it is substantially harder to retrofit than to build in.
What accountability actually requires
A policy saying "every agent action must be traceable to a human" is not accountability. Accountability requires that the responsible person can:
- See what the agent is about to do — before it does it, for consequential actions
- Intervene at the speed the agent operates — review cycles measured in days don't govern systems acting in seconds
- Act without friction — if intervention is buried behind bad tooling, nobody intervenes
- Reconstruct afterwards — via a tool-level audit trail, not a chat log
A manager nominally accountable for an agent that moves faster than they can review, with opaque reasoning and awkward intervention tooling, is accountable in name only.
The practical model
Each agent needs its own identity, tightly scoped credentials, a named human sponsor, and an auditable on-behalf-of chain for every downstream action. Governed execution is the mechanism; tenant isolation is what keeps it honest across customers or business units.
The oversight paradox
One more risk worth naming because it builds slowly. When agents take over pattern recognition, escalation judgement and exception handling, the humans expected to supervise them gradually lose the expertise required to challenge them. Oversight degrades precisely as the thing being overseen expands.
The defence is deliberate: keep humans handling a sample of the work agents do, rotate exception handling, and treat supervisory expertise as something to maintain rather than assume.
Enterprise use cases
Ordered by how reliably they work in production.
Knowledge retrieval and internal orchestration. Finding what the company already knows, across systems, respecting permissions. The fastest-growing enterprise use case and the one that most reliably succeeds, because every answer is checkable and no new access is granted.
Customer support resolution. Reading the account state and taking the action that fixes the issue. High value, high governance requirement.
IT and internal operations. Access requests, common system issues, ticket routing, alert response. A large share of internal time goes to tickets that follow known patterns.
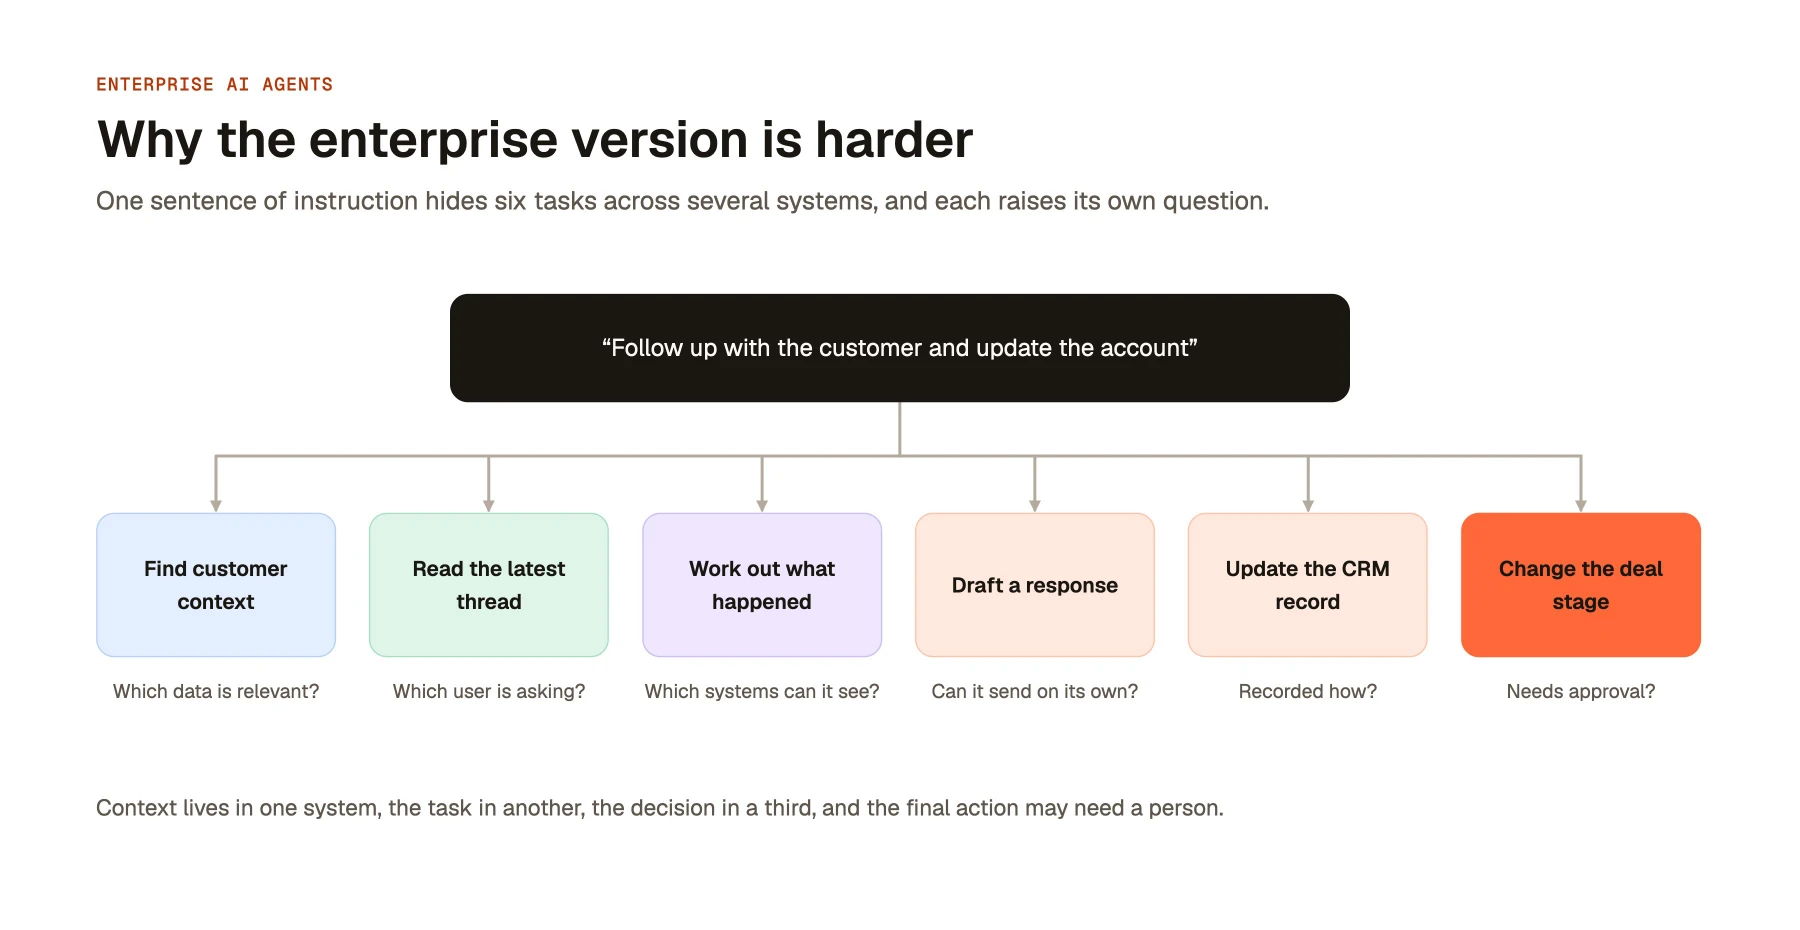
Sales execution. Pipeline hygiene, stale opportunity review, call follow-up, CRM enrichment — the agent carrying context across the whole workflow rather than scoring a lead in isolation. See Sales and AI Agents for Sales.
Finance monitoring and reconciliation. Continuous transaction awareness, anomaly surfacing, variance explanation. Demands clean audit trails, real explainability and hard limits on autonomous action. See Business Intelligence.
Meeting capture and follow-through. Decisions, commitments and owners extracted and tracked. See Meeting Assistant.
Marketing execution. Campaign assembly, performance monitoring, content operations. See Marketing and AI Agents for Marketing.
Legal and compliance review. Surfacing risky clauses, maintaining consistency across documents. Works inside guardrails rather than around them.
A framework for choosing
Not every process wants an agent. The ones that fit share four properties:
- Repeated often enough to justify the setup
- Spans systems — if it lives in one application, that application's automation is cheaper
- Has a checkable output — someone can tell quickly whether it was done right
- Has a bounded cost of error — or can be given an approval gate that bounds it
Processes failing the fourth test aren't disqualified; they need a human in the approval path. Processes failing the third are genuinely poor candidates, because you will never know whether they're working.
Data integration and business logic
An agent is only as good as what it can reach, and only as trustworthy as the logic it applies.
Connect to governed data, not raw data. Pointing an agent at raw tables and asking it to infer your business rules produces confident, inconsistent answers — different numbers for the same question depending on phrasing. Agents should consume data that already has business logic applied.
Read access is not enough. An agent that can only read prepares work; one that can write completes it. The question is not whether to allow writes, but which writes, under what approval.
Permissions must survive the integration. Every connector either preserves the source system's access model or bypasses it. There is no middle option.
Shared context beats per-agent retrieval. Fifty agents with fifty indexes give fifty answers to one question. A single context graph is what makes a fleet coherent (see Context Engineering and Integrations).
Many platforms now standardise tool access through MCP. Useful, but note that a protocol standardises how an agent calls a tool, not whether it should be allowed to. Authorisation remains your problem.
Governance
Most large companies have done the visible part: policies written, risk committees formed, principles mapped to frameworks. The agentic part is different, because it governs behaviour rather than documents.
What a workable programme includes:
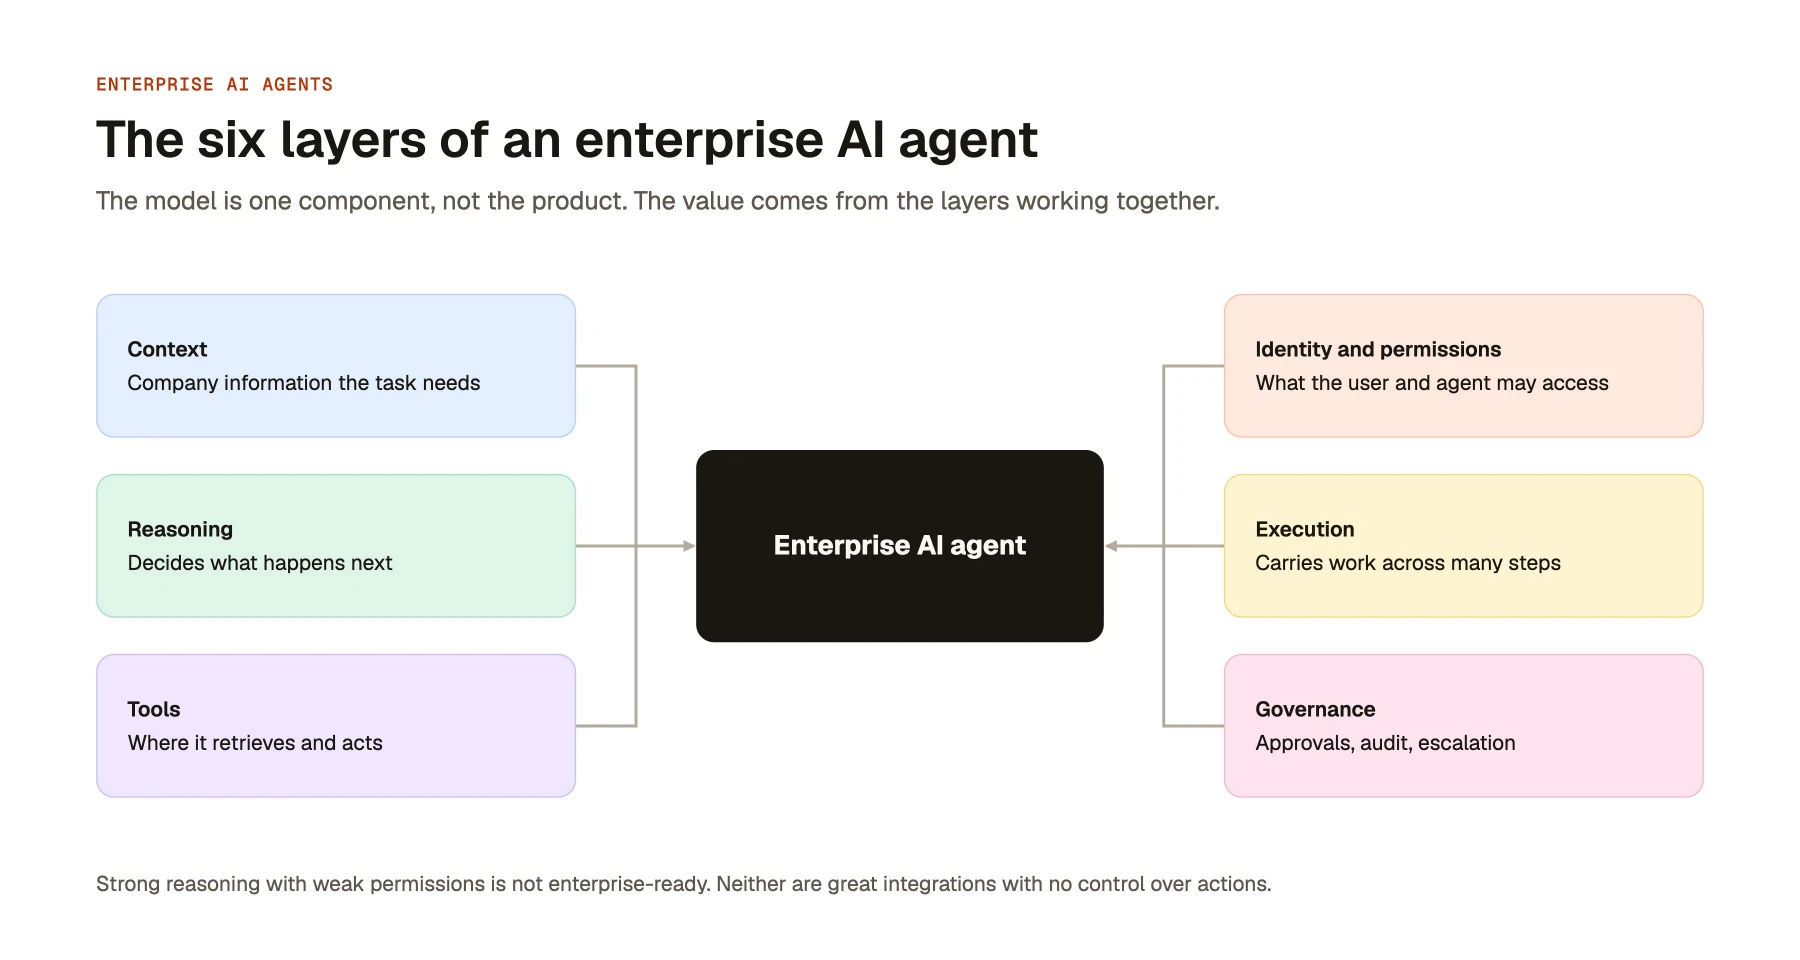
- Certification before deployment. Each agent assessed against behavioural, security and confidence criteria before it goes live — not just at procurement.
- Scoped authority, documented. What this agent may do, to which systems, under whose identity, and where its authority stops.
- Approval gates by action class. Autonomous for reads, approval-gated for writes, blocked for irreversible actions. See approval workflow and human in the loop.
- Continuous evidence, not periodic attestation. The first phase of AI governance was policy, the second process; the third is proof. Logs that demonstrate control was real, continuously.
- Scheduled re-evaluation. Agent behaviour drifts as data, documents and systems change. See evaluation.
- A named owner per agent. Unowned agents accumulate permissions and nobody notices.
Full framework in AI Agent Governance: A Practical Framework for Enterprise Rollout; access model in Permission-Aware AI; threat surface in AI Agent Security.
Evaluating before you deploy
The proof-of-concept trap
POCs almost always outperform production, and the gap is structural rather than anyone's fault.
A POC runs on a curated subset of your knowledge base, a sample of representative queries, and the attention of the vendor's best engineers. Production runs on the full distribution of real requests, connected to systems never designed for AI, managed by people with other jobs. A demo's performance has limited predictive value.
Mitigations: evaluate against the full distribution including the messy tail, connect real systems rather than exports during the trial, and insist the deployment be operable by your team without an open-ended professional services engagement.
Questions that separate vendors
- Does it act on behalf of users, inheriting their permissions per query — or as a service account?
- Is approval configurable per action class, or all-or-nothing?
- Are audit trails queryable for every agent action, at tool-call level?
- What deployment models are supported — cloud, VPC, self-hosted? See Cloud vs Self-Hosted AI Agents.
- What's required before the first useful output — and is professional services mandatory?
- How is quality measured over time, and by whom?
- What's the retention and training-data position, contractually? See zero data retention.
- Can you inspect the context behind a given answer?
What to measure
Distinguish carefully between resolved (the work was completed and stayed completed), deflected (the request went away without being resolved), and escalated (a human finished it). Vendors routinely blend these. Track rework rate — how often a human redoes the agent's work — and cycle time end to end, not task time.
Compliance is not an add-on
For most enterprises the path from POC to production runs through security review, and that is where AI agent projects most often stall or die. Involve security at evaluation, not after selection. The requirements for a system that handles customer data, acts in production systems and operates with autonomy are substantial, and most organisations are less ready than they assume.
What it costs to run
Pricing is where enterprise agent deployments most often surprise people after signature, because the model you choose determines whether adoption is rewarded or taxed.
Four pricing models, four failure modes
Per seat. Predictable, and the easiest to budget. The failure mode is that you pay the same for someone who uses it daily and someone who opens it twice a month — which penalises exactly the company-wide rollout that makes a shared context layer worth having. Teams respond by restricting licences, which starves the thing of the usage it needs to improve.
Per action or per resolution. Aligns cost with value, which sounds right and sometimes is. The failure mode is budgeting: your bill becomes a forecast. It also means a retry costs the same as a success, so you pay most for the cases the agent handles worst.
Consumption or token-based. The least predictable of the four for agentic workloads, for a structural reason: an agent that struggles takes more steps than one that succeeds. You are billed most heavily for your hardest cases, and a quality regression shows up as a cost increase before anyone notices it as a quality problem.
Per team or per workspace. Predictable, and it doesn't tax adoption. The trade-off is less granular cost attribution across departments.
The costs that aren't on the pricing page
- Implementation and professional services. For some platforms this is mandatory and material. Ask whether a deployment is possible without it.
- Connector maintenance. Every integration is a dependency that breaks when an API changes.
- Evaluation. Ongoing, not a launch task. Someone's time, permanently.
- Human review in draft-and-approve. Real cost, usually excluded from ROI models that compare to full automation.
- Re-indexing and permission syncs as your systems and org chart change.
- Rebuilding governance later. The largest hidden cost of all, paid by teams who deployed on service accounts and had to retrofit permission inheritance under audit pressure.
Mid-market economics are different
Most enterprise AI pricing is designed around large seat counts and long implementations. Below roughly a few hundred employees the maths inverts: per-seat pricing stops being competitive against the value delivered, and a mandatory services engagement can exceed the licence itself.
If you're buying at that size, four questions matter more than feature lists:
- Is there a path to production that doesn't require professional services?
- Does pricing scale with team count or seat count? The difference compounds.
- What happens to the bill when usage doubles — and can you model that before committing?
- Is the governance you'll eventually need included, or an enterprise-tier upsell you'll pay for twice?
That last one is the trap. Permission inheritance, audit trails and approval gates are often positioned as enterprise-tier features. Deploying without them and adding them later means rebuilding the integration layer, which is why the cheaper tier frequently isn't.
Libra WorkBase is sold by team rather than per seat, and the governance described throughout this guide — permission inheritance, scoped actions, tool-level audit — is part of the product rather than a tier. See Pricing.
A rollout sequence that works
Phase 1 — Read-only, one team. Knowledge retrieval with permission inheritance and citations. No writes. Establishes trust and generates evaluation data.
Phase 2 — Draft and approve. The agent prepares, a human commits. Most of the efficiency, almost none of the risk, and the edits your team makes show you exactly where it's weak.
Phase 3 — Scoped autonomous actions. One action class at a time, each with a rollback path and monitoring.
Phase 4 — Expand by evidence. Add teams and action classes where phases 2–3 produced data supporting it. Never remove approval globally.
Teams that jump to phase 3 usually rebuild their permission model under pressure, after an incident.
How Libra approaches this
Libra WorkBase runs Agents and Workflows over a shared context layer rather than as isolated bots. Agents act on behalf of users and inherit source-system permissions per query; actions are scoped by class with configurable approval; and every tool call is logged.
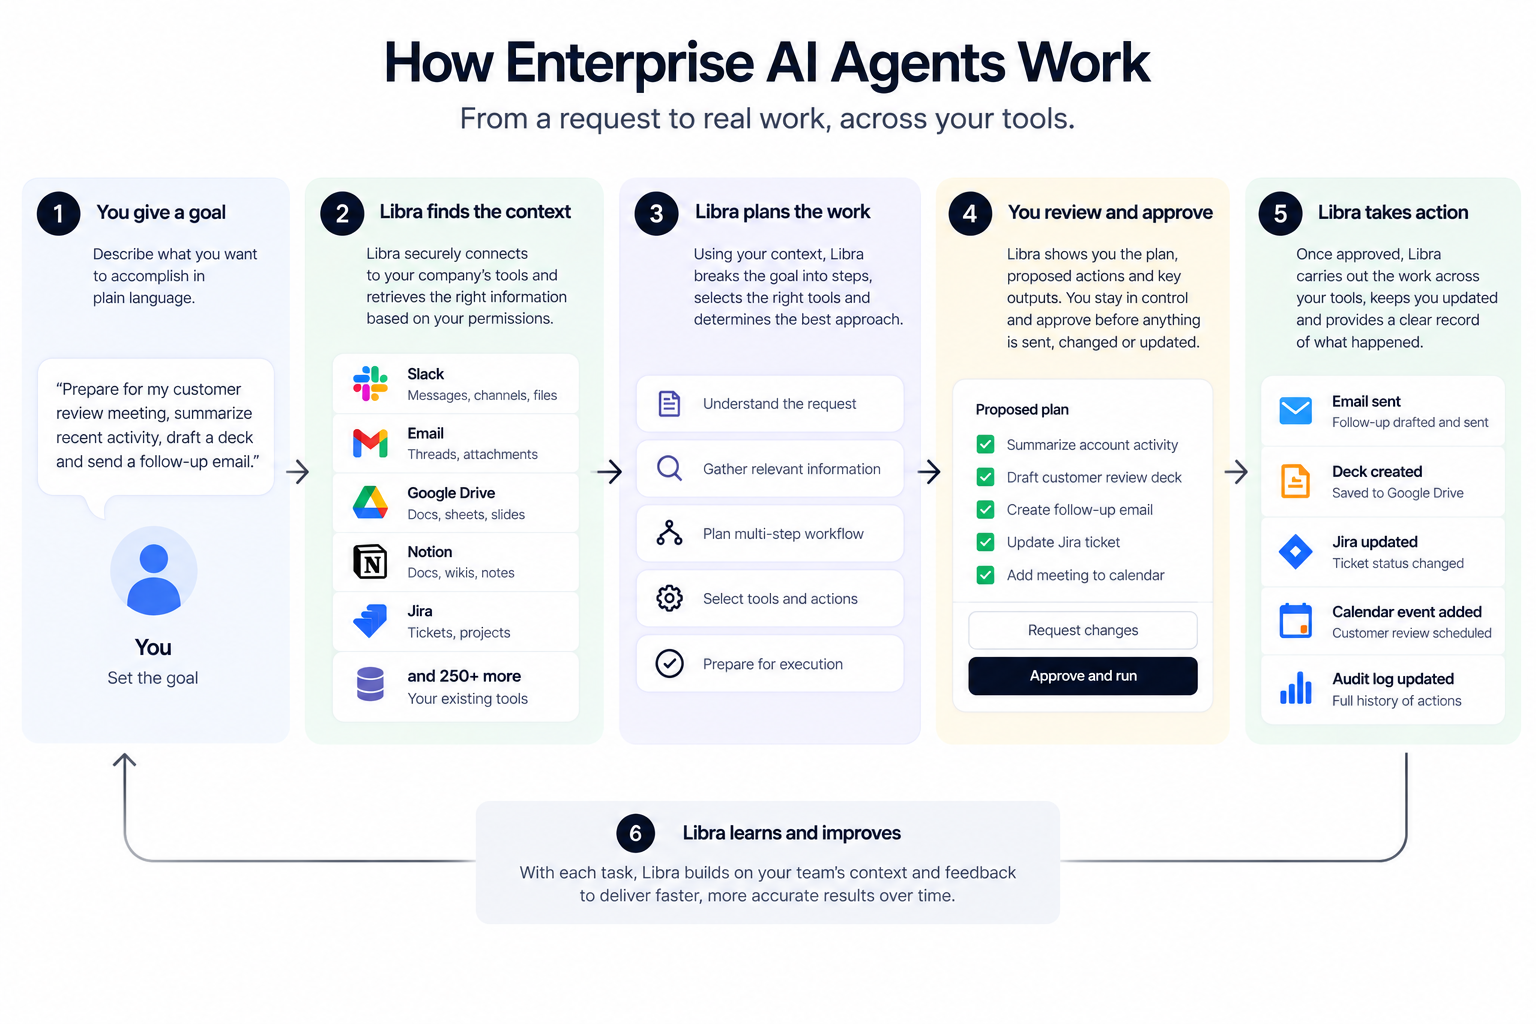
The surfaces agents work across — Knowledge Base, Meeting Assistant, Email Assistant, Business Intelligence — share one context graph through Integrations, so a fleet stays coherent. It deploys to cloud, VPC or self-hosted and is sold by team. See Enterprise for security and deployment detail.
Keep reading
- What Are AI Agents? A Plain-English Explanation
- Agentic AI vs AI Agents: What's Actually Different
- Autonomous AI Agents: How They Work
- How to Build an AI Agent: A Step-by-Step Guide
- Agentic AI Architecture: Core Components Explained
- AI Agent Workflows: How to Structure Work an Agent Can Actually Finish
- What Is Agentic Process Automation?
- AI Agent Security: The Real Risks and How to Evaluate Vendors
- AI Agent Governance: A Practical Framework for Enterprise Rollout
- The Best AI Agent Platform in 2026: How to Run the Evaluation
- Agentic AI Companies to Know in 2026
- AI Sales Agents: Use Cases, Benefits & Examples
- AI Agents for Marketing: Use Cases
- AI agent: definition
- Multi-agent system: definition
- Enterprise Knowledge Management Software: A Buyer’s Guide
Frequently Asked Questions
RPA follows a fixed script against a fixed interface and breaks when either changes. An agent plans, reasons about what to do next and adapts — which makes it flexible and non-deterministic. Use fixed paths where they exist and agents where they don't.
Internal knowledge retrieval with permission inheritance. It grants no new access, produces checkable output, and builds the context layer later use cases depend on.
No. A service account bypasses your permission model entirely. Agents should act on behalf of users and inherit their rights per query.
Yes, with the right deployment model and controls — VPC or self-hosted, permission inheritance, grounded citations, approval gates and tool-level audit. The constraint is architecture, not capability.
Security review, usually because identity and permissions were treated as a later problem. The second biggest is a POC that didn't predict production performance.